Conference on Neural Information Processing Systems (NeurIPS), Main Track
FiLM-CAM: Keyed Feature Modulation for Conditional-Access Watermarking
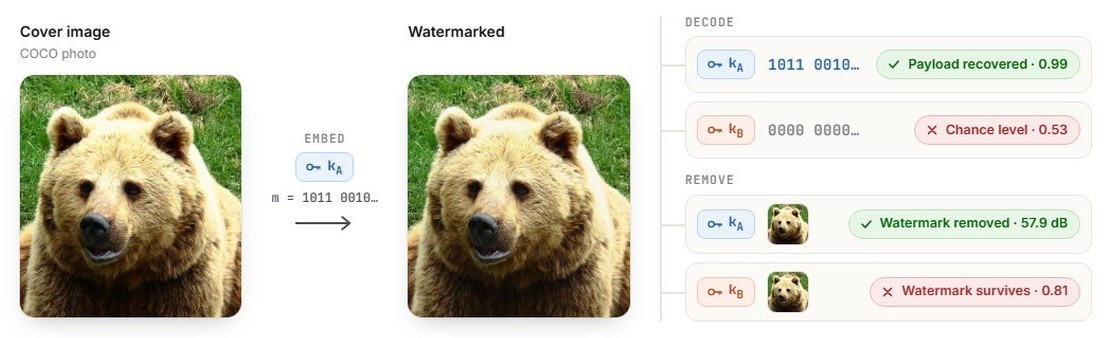
The image is watermarked with key kA. The same key decodes the payload and cleanly removes the watermark. Any other key kB reads nothing, and its removal attempt leaves the watermark decodable. Numbers are COCO results from the paper: bit accuracy for decoding and wrong-key removal, PSNR for correct-key removal.
Overview
Invisible watermarks are increasingly used to flag AI-generated media and to trace provenance. Organisations often don't want those watermarks to be open to all: they want to control who can embed, read and remove them. Today that means training and shipping a separate private model for every organisation.
We propose FiLM-CAM, a conditional-access image watermarking approach that enforces authorised encoding, decoding and removal through keyed feature modulation. A secret key conditions a Feature-wise Linear Modulation (FiLM) mechanism that transforms the internal representation of the watermark signal before embedding, coupling the payload to the key at the feature level rather than the pixel level. The same key must be presented to the decoder to recover the payload. We train the system to maximise the gap between authorised and unauthorised use, so extraction is reliable under the correct key and fails under incorrect keys.
The encoder is also trained to estimate the watermark residual regardless of whether a watermark is already present. Removal then needs no extra network: re-encode, subtract the residual, and refine iteratively, provided you hold the key. We evaluate FiLM-CAM across multiple encoder–decoder backbones and show that keyed feature modulation is an effective, architecture-agnostic conditional access module (CAM) for image watermarking.
Key Contributions
Keyed Feature Modulation
A lightweight Conditional Access Module (CAM) injects the key into the internal features of the embedder and extractor. A 100-bit key passes through a 3-layer MLP $\phi$ to a 64-d embedding shared by both networks, and a linear layer $\psi$ produces channel-wise scale and shift terms, applied at the embedder bottleneck and right before the extractor's prediction head:
Each training iteration also adds a wrong-key step whose target is an invalid all-zero codeword, widening the gap between authorised and unauthorised decoding.
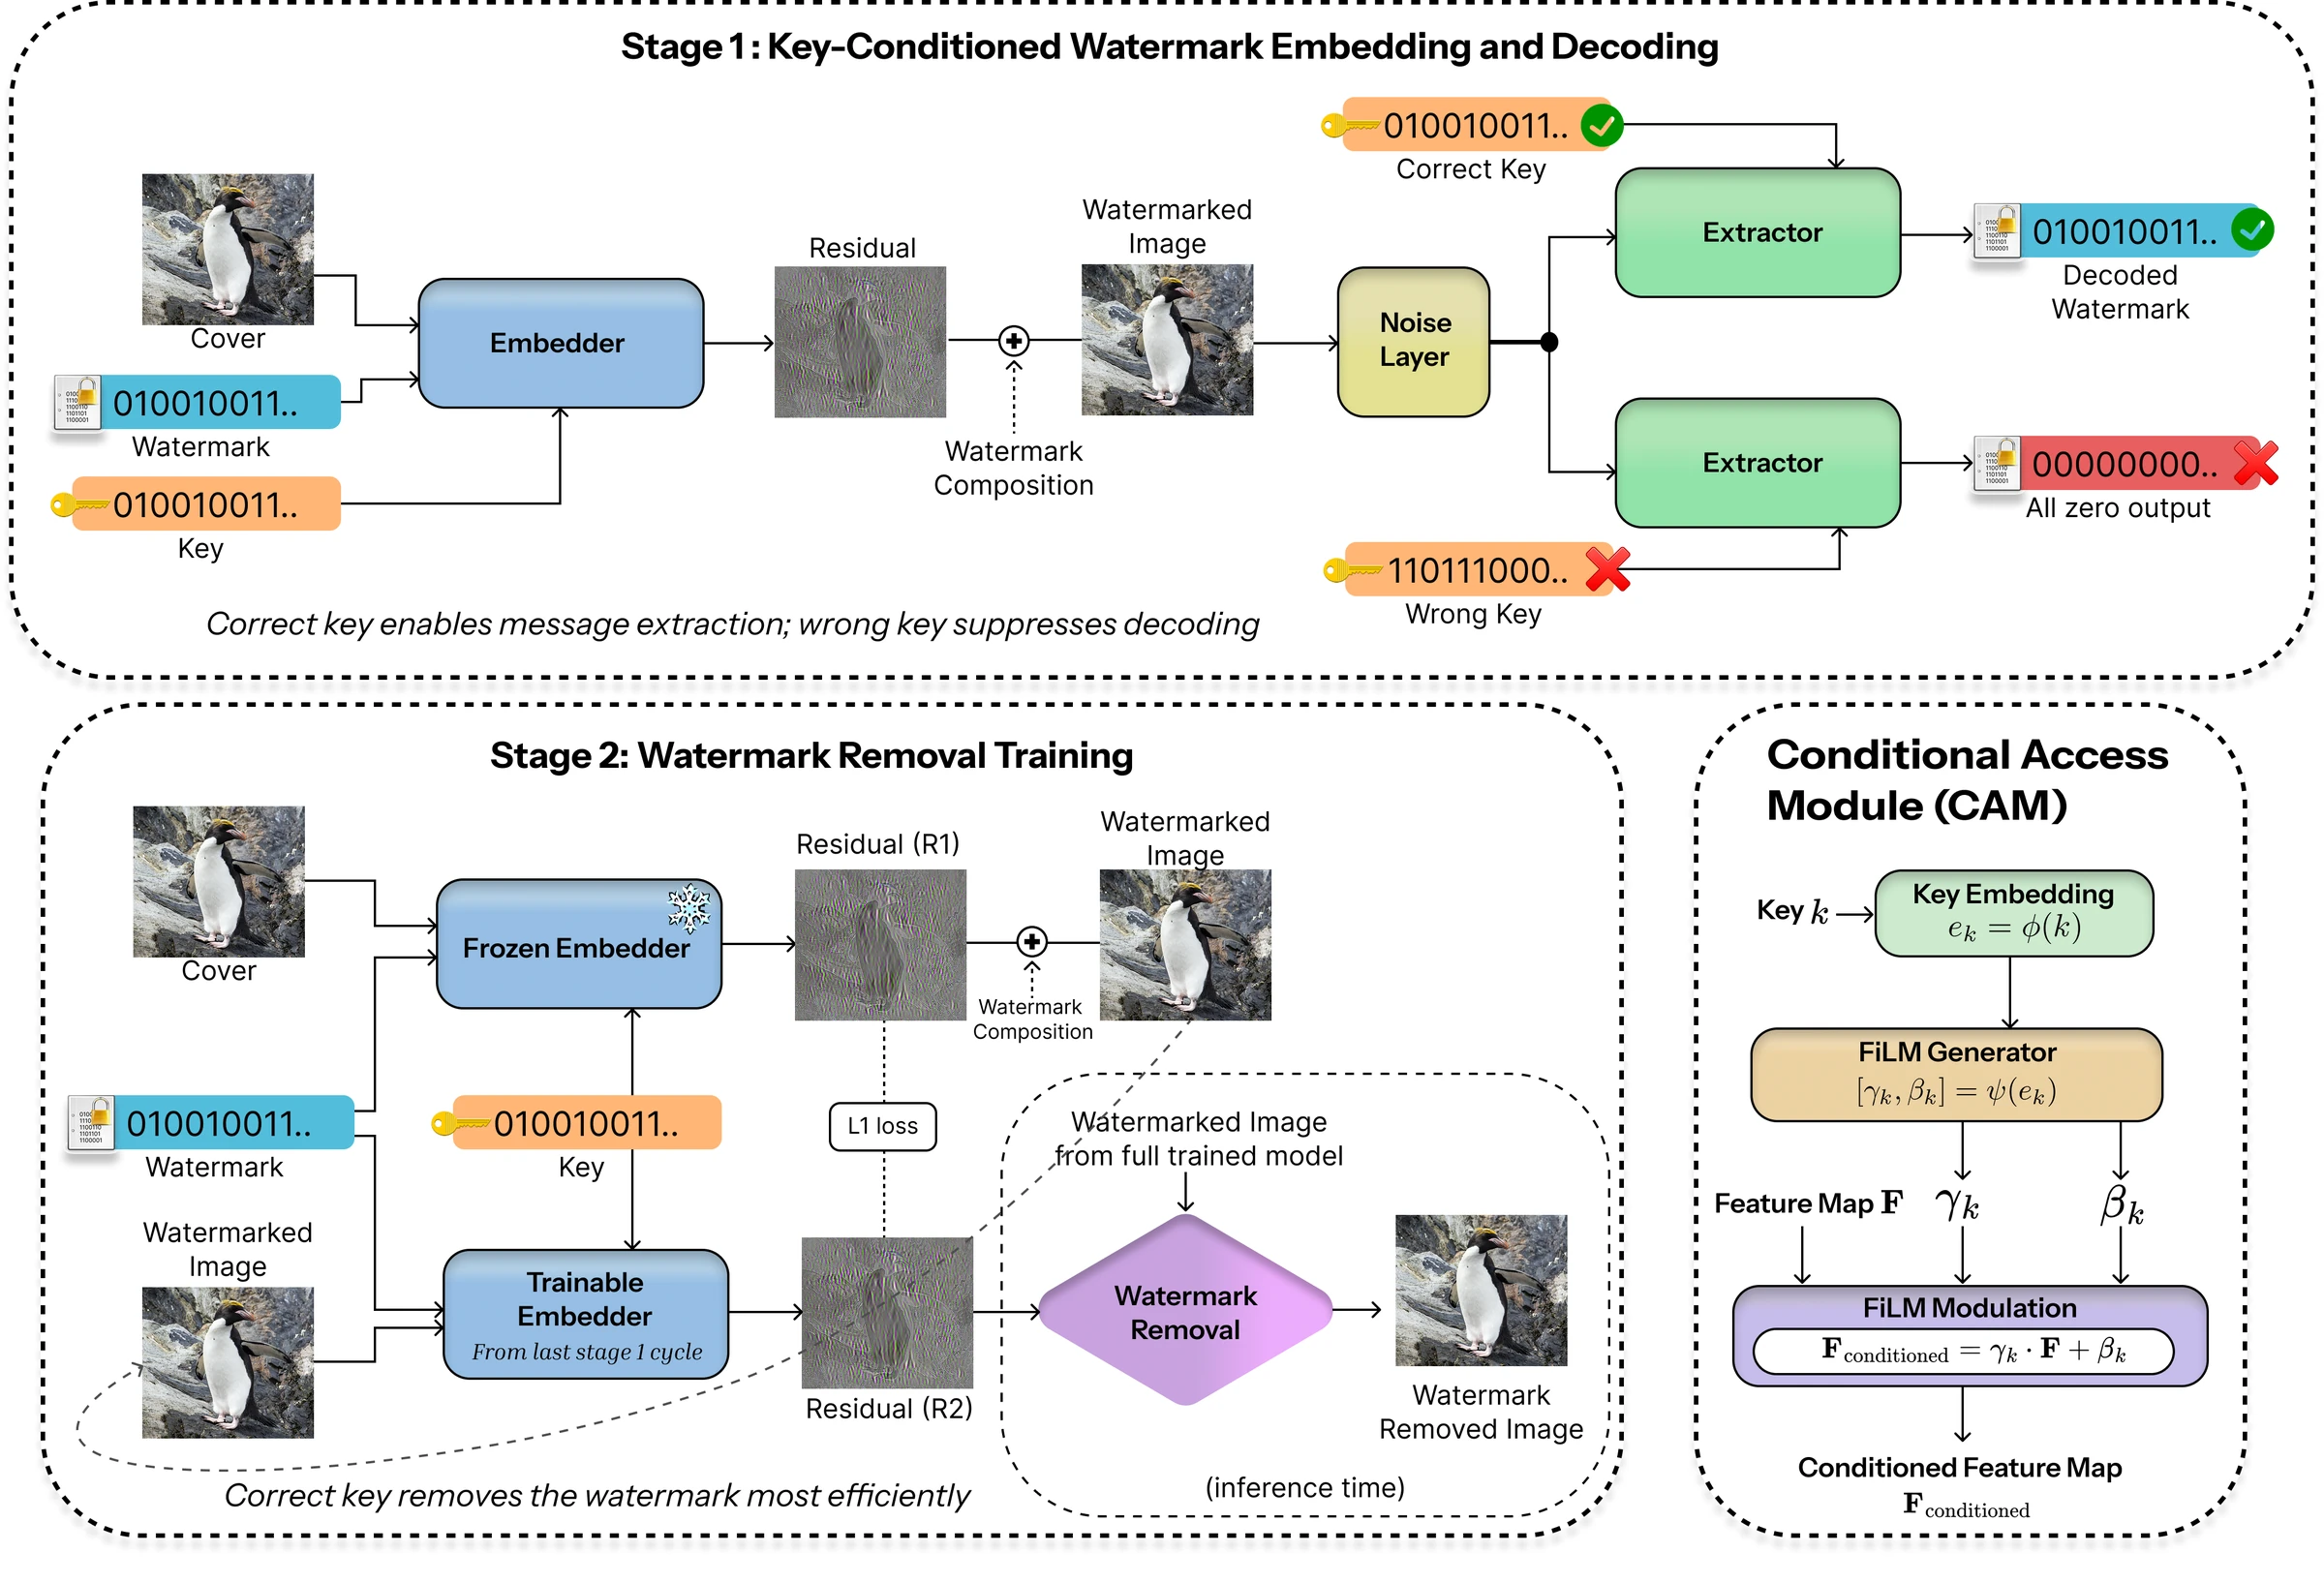
Stage 1: the embedder predicts a residual that is composed with the cover image. The extractor recovers the watermark only with the correct key and outputs an all-zero message otherwise. Stage 2: a trainable copy of the embedder learns to output the same residual when given the watermarked image, so it can be subtracted to remove the watermark. CAM: the key $k$ is embedded as $e_k = \phi(k)$, projected to $(\gamma_k, \beta_k)$, and used to modulate intermediate feature maps.
Logit-Space Composition
The residual is added in an atanh-transformed space with an image-dependent gain. Composing there gives cleaner, more invertible removal than plain pixel addition. In ablations, additive composition embeds just as well but removes less cleanly (54.1 vs. 55.4 dB removal PSNR on DIV2K), and dropping the gain costs over 10 dB in both watermarked and removal quality.
Key-Conditioned Removal
The embedder is reused to estimate the watermark residual, so removal needs no extra network. A frozen Stage 1 embedder produces the reference residual. A trainable embedder sees the watermarked image and must reproduce that residual in logit space under the correct key, and shrink it to zero under a wrong key:
The two stages alternate in 5-epoch cycles. With the right key the residual is subtracted cleanly; with a wrong key the watermark stays decodable.
Results
Conditional Decoding
With the correct key, FiLM-CAM decodes ~99% of bits at 46.6–48.2 dB PSNR on COCO, DIV2K and SA-1B, comparable to or better than state-of-the-art neural watermarking methods. With a wrong key, bit accuracy drops to 0.53–0.55, where 0.50 is chance level.
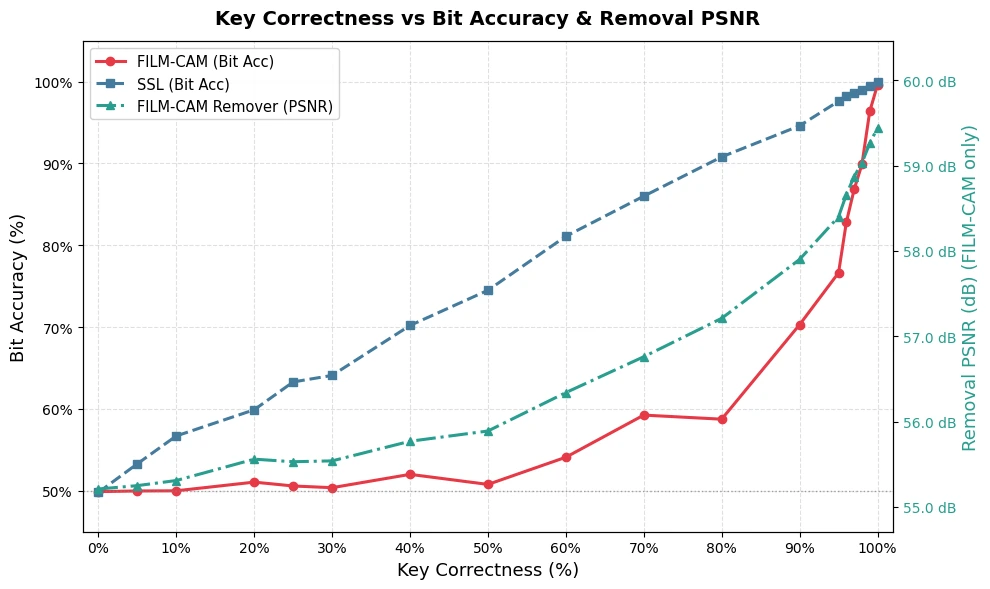
Bit accuracy as a function of key correctness, the share of query-key bits that match the true key. SSL leaks the payload gradually as the carrier gets closer. FiLM-CAM stays near chance up to ~80% key correctness, then climbs steeply to ~99% for the exact key. Removal PSNR (green, right axis) also improves only as the key approaches the true one.
Watermark Removal
Regeneration-based removal attacks reduce post-removal bit accuracy to chance but reach only 20–31 dB PSNR. With the correct key, FiLM-CAM removes the watermark at 54.0–57.9 dB PSNR in 5 ms. With a wrong key, post-removal bit accuracy stays at 0.78–0.81, so the watermark survives an unauthorised removal attempt.
Clean removal also makes re-watermarking practical. Stacking new watermarks on top of each other accumulates distortion fast, while embedding, removing and re-embedding keeps both the watermarked and recovered images close to the original over ten cycles.
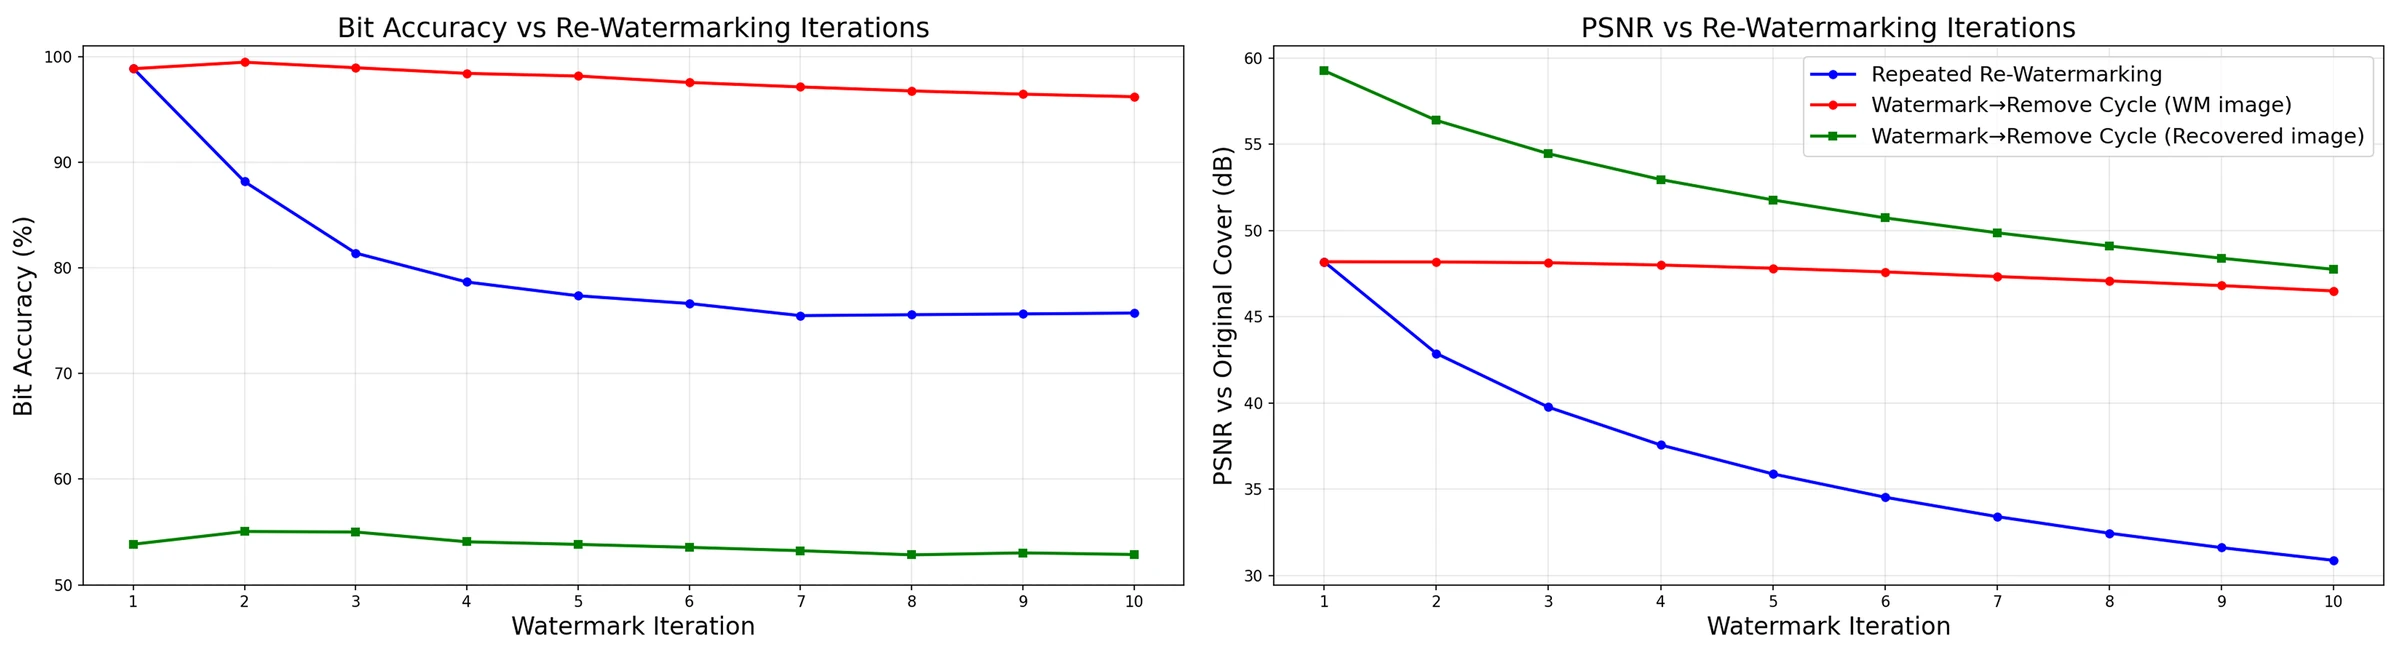
Left: bit accuracy over iterations. Naïve repeated watermarking (blue) degrades to ~75%, while the watermark→remove cycle (red) stays above 96%. On the recovered images (green), accuracy stays near chance, so each removal works. Right: PSNR against the original cover. Repeated watermarking falls to ~31 dB, while the cycle keeps the watermarked image near 47 dB and the recovered image between 59 and 48 dB.
Robustness & Limitations
The noise-trained variant of FiLM-CAM reaches a mean bit accuracy of 96.0% across 21 perturbations on DIV2K, second to PixelSeal (98.0%). The lowest accuracies are under JPEG compression (85.1%) and grayscale conversion (75.7%).
Conditional access prevents key-free decoding and key-free reconstructive removal, but not key-free destruction. Overwriting with another key, or strong diffusion-based regeneration, can disable detection without the key, as with learned watermarking in general. Such attacks do not recover the original cover image.
The interactive project page has the full comparison tables, a robustness heatmap and an image viewer with 18 COCO examples.
BibTeX
Acknowledgements
This research was funded in part by Adobe Research and in part by DECaDE under the UKRI/EPSRC Grant reference EP/T022485/1.